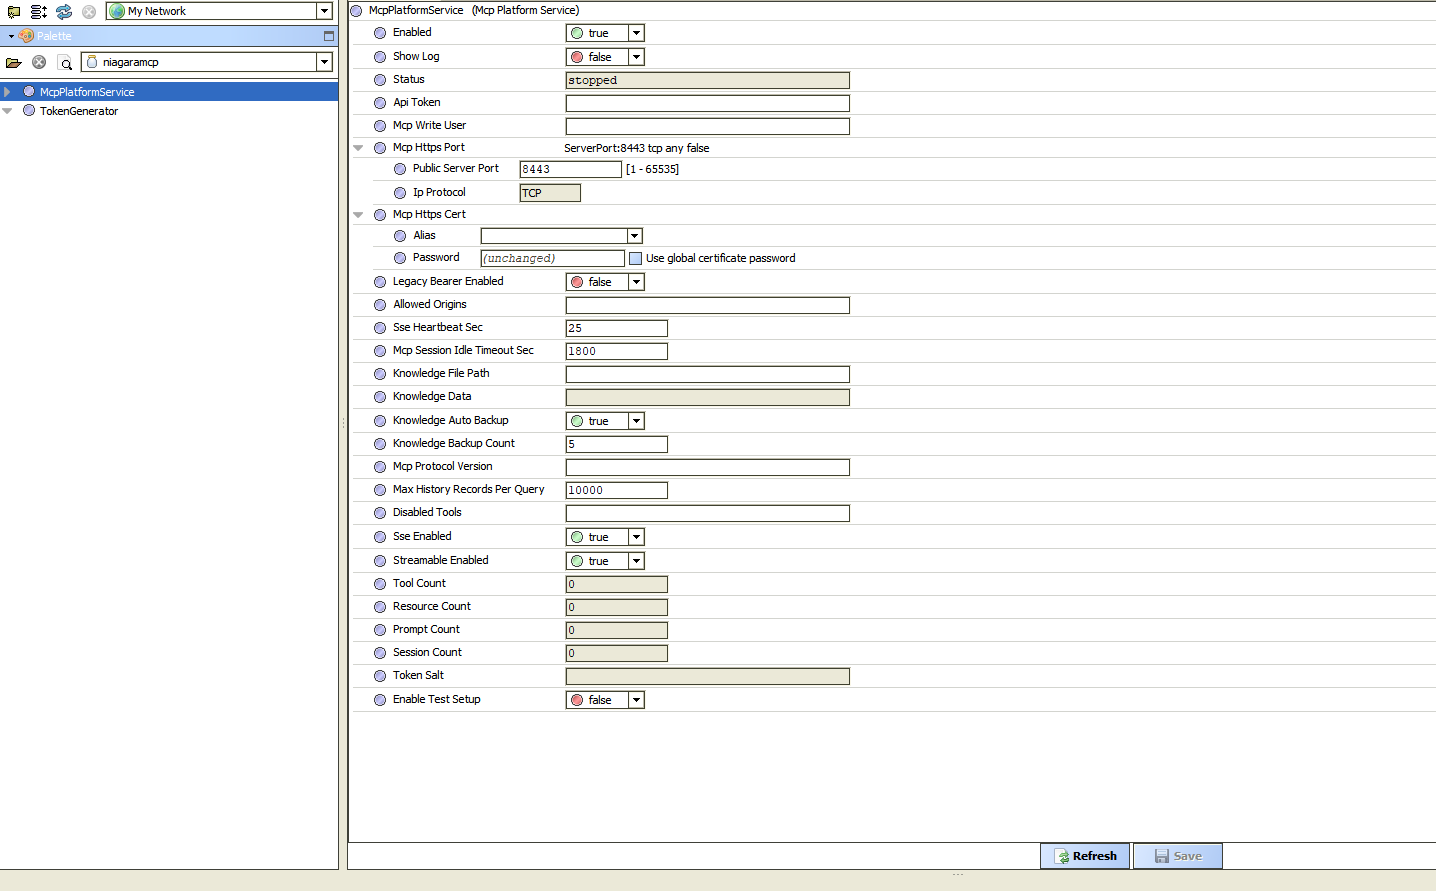
A_I_agent.bog (69.0 KB)

USER MANUAL: Niagara ProgramObject “Gemini Agent”
-
What it is

This ProgramObject sends a single request to Google Gemini when you press updateNow and receives a text answer.
It can automatically build a “station snapshot” (points/folders) and, optionally, add history data (BQL).
Important: the read-only version does NOT write values to points and does NOT execute /set. -
What happens on updateNow (request flow)
- Checks enable.
- If the model list has not been loaded yet, it loads models first and then automatically continues with the request.
- Collects:
- STATION_SNAPSHOT_JSON from pointsOrds
- STATION_HISTORY_JSON from historyBqlOrds (if provided)
- Builds the request:
- systemInstruction = instructions (except for gemma models; see below)
- contents = (chat memory, if enabled) + current user text (prompt + snapshot + history)
- Sends HTTP POST to the generateContent endpoint.
- Writes results:
- outText = model answer (or ERR: …)
- answerOk = true/false
- statusMessage = short status + tokens (if Gemini returns usage)
The block sends requests only on updateNow. It does not call the API in the background by itself.
-
Quick start in 5 minutes

Step 1. Create the ProgramObject and add the slots (see section 4).
Step 2. Put your Gemini API key into apiKey.
Step 3. Press refreshModelsNow (or press updateNow; it can fetch models automatically).
Step 4. Pick a model in modelPick (or type it into model).
Step 5. Fill pointsOrds (folders/points, one ORD per line).
Step 6. Write your task in prompt (if empty, it uses “Analyze station data.”).
Step 7. Pulse updateNow = true.
Read the answer in outText and check statusMessage. -
Slots: what they do (core)

Control
- enable (BBoolean). false = block does nothing, resets buttons, cancels pending work.
- updateNow (BBoolean, one-shot). Sends one request. Returns to false automatically.
- refreshModelsNow (BBoolean, one-shot). Refreshes the model list.
- restartNow (BBoolean, one-shot). Soft restart: cancels pending work, clears 429 pause, resyncs model selection.
- clearMemoryNow (BBoolean, one-shot). Clears chat memory (chatMemory).
Access
- apiKey (BString). Gemini API key.
Instructions and prompt
- instructions (BString). “System” instructions (systemInstruction). For gemma models these are injected into the user text.
- prompt (BString). Task text. If empty, “Analyze station data.” is used.
- maxOutputTokens (BInteger). Max output tokens. Default 400. Range: 50…8192.
Model
- modelPick (BDynamicEnum). Dropdown of models (filled after refreshModelsNow).
- model (BString). Model id (e.g., gemini-1.5-pro). If you paste “models/…”, the prefix is removed.
- modelsList (BStatusString). Text list of models (after refresh).
- modelsLastUpdate (BAbsTime). Timestamp of last model refresh.
Chat memory
- memoryModePick (BDynamicEnum). What to store in memory (see section 7).
- memoryMaxMessages (BInteger). How many last messages to keep (0…200). Default 12.
- chatMemory (BStatusString). Memory storage as text (usually view-only).
Outputs
- outText (BStatusString). Model response or “ERR: …”.
- answerOk (BBoolean). true only after a successful response.
- statusMessage (BStatusString). State: loading/sending/success/ERR/paused + tokens.
- Station snapshot: pointsOrds + limits

pointsOrds (BString): list of ORDs, one per line.
You can pass:

- a point ORD (often ends with /out)
- a folder ORD (the block walks it recursively and collects points)
Examples:
- station:|slot:/Drivers/BacnetNetwork/AHU_1/points
- station:|slot:/Drivers/BacnetNetwork/AHU_1/points/Sensors/SupplyTemp/out
- station:|slot:/Drivers/OpcUaNetwork/Line1/points
Optional human label prefix
You may put a label before “station:”
- Room12_station:|slot:/Drivers/OpcUaNetwork/SB_A1/points
“Room12” is attached to the produced names and helps separate similar devices in different areas.
Limits and filters (auto-created after first run)
- snapshotMaxPoints (BInteger). Default 2500, range 10…5000.
- snapshotMaxDepth (BInteger). Default 25, range 1…50.
- ignorePointNames (BString). Blacklist of exact point names, comma-separated: Temp, Hum, CO2.
- ignoreFolderNames (BString). Blacklist of exact folder names, comma-separated: Diagnostics, Alarms.
Snapshot JSON format
The request includes JSON like:
{“groups”:[{“folders”:[…],“points”:[ “…”, “…” ]}, …]}
Each point becomes a line like:
“<path/prefix><Identifier - >PointName = value unit”
Numbers use 2 decimals, text/enums are cleaned from newlines, long strings are truncated.
Optional: groupFormat
If you add slot groupFormat (BString) and set a BFormat string, the block groups points using that format.
If you do not know BFormat, skip it; default grouping is usually fine.
- History: historyBqlOrds

History is added only if historyBqlOrds is not empty.
Format: one BQL-ORD per line.

Example:
- Room201_history:/PS/M12K4VAS01$20Sensor_TE_201_1?period=last7days|bql:select timestamp, value
You can also add a label prefix before “history:”
- Room201_history:history:/PS/Temp?period=last24hours|bql:select timestamp, value
Parameters (auto-created after first run)
- historyMaxRows (BInteger). Default 100, range 1…50000. Sends last N rows.
- historyMaxSeries (BInteger). Default 20, range 0…100. How many series to include.
Soft JSON size limit: 180000 chars. If exceeded, the block stops adding more series.
What is sent per series
For each series the block tries to resolve a table (BITable) and sends:
- ord (string)
- name (series name derived from ORD + prefix)
- columns (column names)
- rows (last N rows)
- min/max/avg/last for column “value” (if numeric)
- count (rows actually sent)
If the ORD does not resolve to a table, the series gets an “error” field (e.g., not_table).
- Chat memory: how to use

Memory works like this:

- Before sending, the block adds previous messages from chatMemory into contents.
- After a successful response, it updates chatMemory.
Enable/disable
- memoryMaxMessages = 0 → memory off.
- memoryMaxMessages > 0 → memory on (default 12).
memoryModePick (what to store)
0) prompt_only — store prompt only
- snapshot_only — store station snapshot only
- answers_only — store model answers only
- prompt_snapshot — prompt + snapshot
- prompt_answers — prompt + answers
- snapshot_answers — snapshot + answers
- prompt_snapshot_answers — everything
Clear
- clearMemoryNow = true → chatMemory becomes empty.
Note
Snapshot and history can be large. If you store snapshot in memory, it grows quickly and you hit token/quota limits sooner.
For long-term use, prompt_answers or answers_only is usually enough.
- Models: refresh and selection


- refreshModelsNow updates modelsList and fills modelPick.
- updateNow can also fetch models automatically if the list is empty.
- If model is empty or not found, the block uses the first model from the list.
- For gemma models the block does not use systemInstruction; it prepends instructions into the user text instead.
- Status messages
statusMessage examples:
- “Models: loading…” — fetching model list
- “Models: updated” — model list refreshed
- “Analyze: preparing…” — building snapshot/history/request body
- “Analyze: sending…” — request sent, waiting for response
- “Analyze: success | Tokens: …” — success + token usage (if returned)
- “Analyze ERR: …” — error
- “Analyze paused (429).” — paused due to rate limit/quota
outText:
- model answer on success
- “ERR: …” on error
- “Pause (429) until ms=…” while paused (Unix time in ms)
- Troubleshooting


apiKey empty
- Fill apiKey. Ensure no spaces/newlines inside the key.
Models ERR: …
- Often invalid key or no API access.
- Check that Gemini API is enabled in your Google project and that quota is available.
Analyze ERR: model empty
- Pick a model: refreshModelsNow → modelPick, or type model manually.
ERR: HTTP 401/403
- Invalid key, API disabled, no billing/quota, or access restrictions (project/region).
ERR: HTTP 429 (quota/rate limit) 
- You hit a rate limit or your quota is exhausted.
- The block pauses automatically:
- ~2 minutes for “normal” 429 (rate limit)
- ~30 minutes for quota/RESOURCE_EXHAUSTED
- To recover:
- restartNow (clears local pause) and retry later
- reduce load: fewer updateNow presses, fewer points/history, lower maxOutputTokens
- fix the cause in Google console (quota/billing/limits)
PARSE_ERR
- Gemini returned an unexpected JSON shape. outText contains RAW excerpt. Often fixed by switching model or refreshing models.
history error: not_table
- Your historyBqlOrds does not resolve to a table. Verify the BQL-ORD; it must return BITable.
Empty station snapshot
- pointsOrds are wrong/unresolved or not pointing to /points or a point.
- Verify each ORD in Workbench (Resolve/Go To).
- Remove extra characters at the start of the line. The block trims trailing “)” but does not fix leading junk.
- Load and safety


- apiKey is stored in a slot. Do not show it on PX pages without protection.
- Bigger pointsOrds and higher historyMaxRows produce larger requests and hit limits faster.
- Typical “daily analysis” settings:
- snapshotMaxPoints 200…800
- historyMaxRows 50…200
- memoryMaxMessages 6…20, mode answers_only or prompt_answers
- Where to improve next


- Show 429 pause time as station time (not Unix ms).
- Add internal throttling for updateNow to avoid button “bounce”.
- Add snapshot/history caching (do not resend if unchanged).
- Add “quick/full analysis” profiles (a single switch that sets the limits).